# Anthropic’s Mandatory Text Watermark Isn't Killing AI SEO. It’s Killing $20 Prompt-Wrappers.
## The 15-Million-Euro Panic Button
If you're evaluating the impact of the Anthropic text watermark on your Google SEO strategy, you're likely staring at the wrong problem. The panic sweeping the industry isn't about AI detection. It's about a fundamental misunderstanding of compliance, risk, and algorithmic behavior.
### Understanding the Anthropic Text Watermark and Article 50
The Anthropic text watermark is a statistical bias deliberately injected into token selection probabilities during AI generation, implemented specifically as a compliance mechanism to avoid fines of up to €15 million or 3% of global revenue under Article 50 of the EU AI Act.
That single sentence explains the origin of the panic.
AI labs aren't watermarking text because they want to. They're doing it because the European Union forced their hand. Article 50 of the EU AI Act isn't a suggestion. It's a financial guillotine. For a company like Anthropic, non-compliance means facing catastrophic penalties. They had to act. And their solution was to alter the mathematical probability of the words their models choose, embedding an invisible, statistical signature into every output.
The SEO industry's reaction has been predictably hysterical.
Marketers assume Google will instantly crawl this watermarked content, flag it as AI, and nuke their rankings. They envision a dystopian future where every piece of Claude-generated text carries a scarlet letter, instantly recognizable by search algorithms.
This assumption is technically flawed. It demonstrates a complete lack of understanding regarding how probabilistic watermarking actually functions in the wild.
We aren't dealing with a visible stamp. We're dealing with token bias. And token bias, as Anthropic themselves admit, is surprisingly fragile.
The panic is real. But the target of that panic is entirely misplaced.
## The False God of Manual Rewriting
Agencies are actively sabotaging their own margins. They dump a single, generic prompt into Claude 3.5 or Sonnet 5, wait thirty seconds, and copy-paste the raw output directly into a WordPress editor. Then, they act surprised when probabilistic analysis tools flag the entire domain. The statistical watermark is sitting right there, completely intact, screaming to be found.
### Why Basic Prompting Fails the Probability Test
The immediate reaction across the industry has been a masterclass in technical ignorance. Marketers are hitting the panic button, abandoning automated workflows entirely and reverting to prehistoric manual writing processes because they don't understand how the underlying mechanism actually functions.
This knee-jerk regression explodes customer acquisition costs.
Returning to manual drafting isn't a strategic pivot. It's a costly admission of defeat driven by a fundamental misunderstanding of the technology. The core issue isn't that AI is inherently flawed or that the EU AI Act has destroyed automated content generation. The problem is the lazy, single-pass generation model.
When you use a $20-a-month prompt-wrapper, you are relying on a system that generates text in a single, continuous flow. This unbroken stream perfectly preserves the statistical bias—the watermark—that Anthropic is legally obligated to inject. The token selection probabilities remain exactly as the model intended them to be, making detection trivial for any basic probabilistic scanner. The failure point isn't the AI. It's the workflow that treats complex language models like a magical vending machine.
## Google Doesn't Hate AI. It Hates a Lack of Information Gain.
### The Threshold for Breaking Token Probability
Anthropic's technical documentation reveals that their text watermark—a statistical bias in token selection—is highly fragile and effectively destroyed when the generated text undergoes heavy editing, multi-stage fragmentation, or the injection of external data.
We've analyzed Anthropic's own engineering notes. They aren't hiding this. The watermark is a delicate mathematical construct. It relies on a continuous, uninterrupted sequence of probabilistic choices. Break that sequence, and you break the signal.
Google's Helpful Content Update didn't introduce a penalty for the presence of a watermark. It introduced a penalty for the absence of value. The algorithm targets low-effort, repetitive outputs that offer zero new insights. It targets content that looks exactly like the millions of other pages generated by the same raw prompt.
This is the reality the industry refuses to accept. The watermark only survives in raw, unedited, lazy outputs. If your content is retaining the watermark, it isn't because Anthropic's detection is flawless. It's because your generation process is flawed. You aren't editing. You aren't adding data. You're just copying and pasting.
When text is fragmented across multiple generation stages, the statistical bias is diluted. When external data—proprietary research, internal metrics, real-world constraints—is injected into the prompt, the token probabilities shift. The watermark relies on the model's default assumptions. Force the model to work with your specific data, and those default assumptions are overridden.
We don't need to fear the watermark. We need to fear the lazy workflows that allow it to survive. The focus shouldn't be on evading detection. The focus must be on forcing the AI to generate content that is structurally immune to detection because it is fundamentally unique.
## The Asynchronous Multi-Agent Pipeline
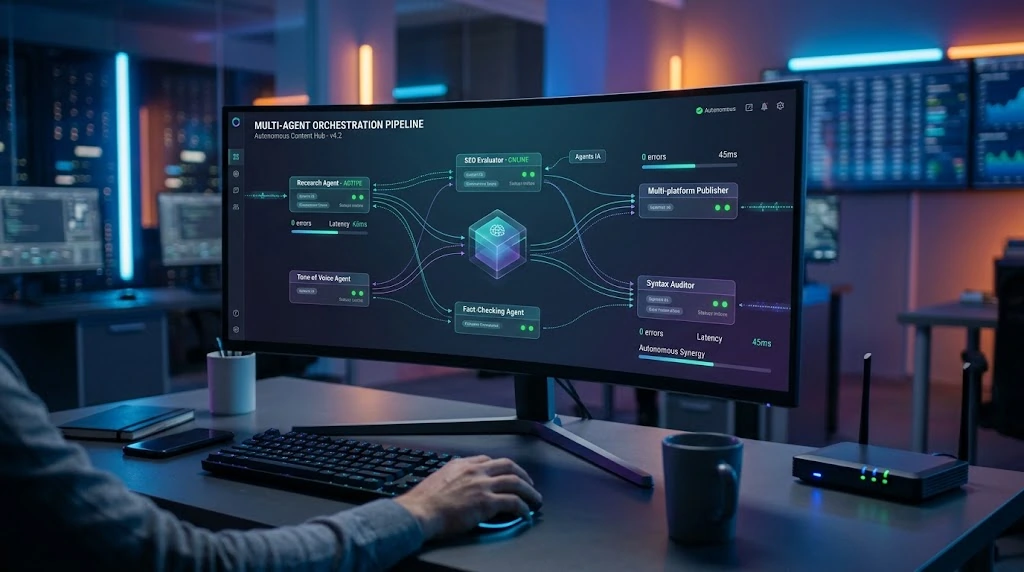
Stop throwing single prompts at Claude. It won't work. It's a guaranteed way to get flagged, penalized, and outranked. The only viable path forward is building a pipeline. An asynchronous, multi-agent architecture.
### Architecting Immunity: From SERP Research to Fact Audits
We need to move beyond the single-pass generation model. The modern workflow requires a multi-stage process, specifically designed to inject unique data and shatter statistical watermarks.
First, you execute deep SERP research. You aren't just looking at the top 10 results; you are extracting the core entities, the semantic relationships, the hidden queries that the current content fails to answer. You extract this raw, unstructured data.
Next, you slice the topic. You don't feed the entire research block into an LLM and ask for an article. You break it down into an entity graph. You map the logical flow, isolating specific claims and arguments into distinct nodes. This fragmentation is vital.
Then comes RAG editing. Retrieval-Augmented Generation. You feed these isolated nodes into specialized agents, pulling in external data, proprietary benchmarks, and specific author perspectives. The AI isn't writing from scratch; it's synthesizing injected facts. This heavy editing process completely disrupts the token probability sequence Anthropic relies on.
Finally, the factual density audit. A separate agent reviews the output, cross-referencing every claim against the initial entity graph. It strips out fluff, enforces the required information gain, and ensures the semantic density is high enough to satisfy search intent without triggering probabilistic flags.
### Evaluating Content Generation Architectures
Basic $20 prompt-wrappers are fundamentally broken in this new reality. Tools that simply pass a user prompt to an API and return raw text are generating the exact statistical bias the EU AI Act mandates. They provide zero information gain and guarantee detection.
Pipeline architectures are different. They don't just generate text; they engineer information. By breaking the generation process into asynchronous steps—research, fragmentation, RAG injection, and auditing—they produce content that is statistically indistinguishable from heavily researched human writing. They don't just bypass the watermark; they build content that Google actually wants to rank.
## The Death of the $20 Prompt-Wrapper
### Automating the Pipeline Without the Technical Debt
Reverting to manual writing is a panicked regression. It isn't a strategy. It's a surrender to technical ignorance that instantly explodes customer acquisition costs.
Modern teams don't retreat to prehistoric workflows just because the regulatory environment shifted. They adapt the infrastructure. The problem isn't AI generation; the problem is the fragile, single-pass generation models that defined the early era of generative SEO. Those models are dead. The $20 monthly subscription to a basic AI wrapper that spits out raw, watermarked text is a liability, not an asset.
We know the statistical bias embedded by Anthropic shatters under multi-stage fragmentation and external data injection. The challenge is execution. Building and manually maintaining custom edge middleware to handle SERP research, entity extraction, RAG editing, and factual auditing is incredibly resource-intensive. It requires specialized engineering talent that most marketing teams lack.
This is the infrastructure gap. Instead of manually configuring custom edge middleware, platforms like HighStory automate the entire pipeline, ensuring high Information Gain and zero watermark retention. You bypass the technical debt while maintaining the scale and efficiency of automated content generation.
The market is correcting itself. The noise is being filtered out. By Q4 2026, single-prompt SEO tools will be entirely obsolete.
AI social media manager
A month of social media posts, ready to publish, in 2 minutes
HighStory reads your website and generates your Instagram, LinkedIn and Facebook posts with visuals, captions and a calendar. You approve, it publishes.