# Buy SearchGPT Ranking Software: The $40K Citation Trap
Enterprise software buyers routinely authorize five-figure procurement budgets for rank tracker upgrades promising visibility metrics inside OpenAI's search environment. The sales collateral showcases tidy dashboards displaying numerical positions across target commercial prompts.
Then the technical audit happens.
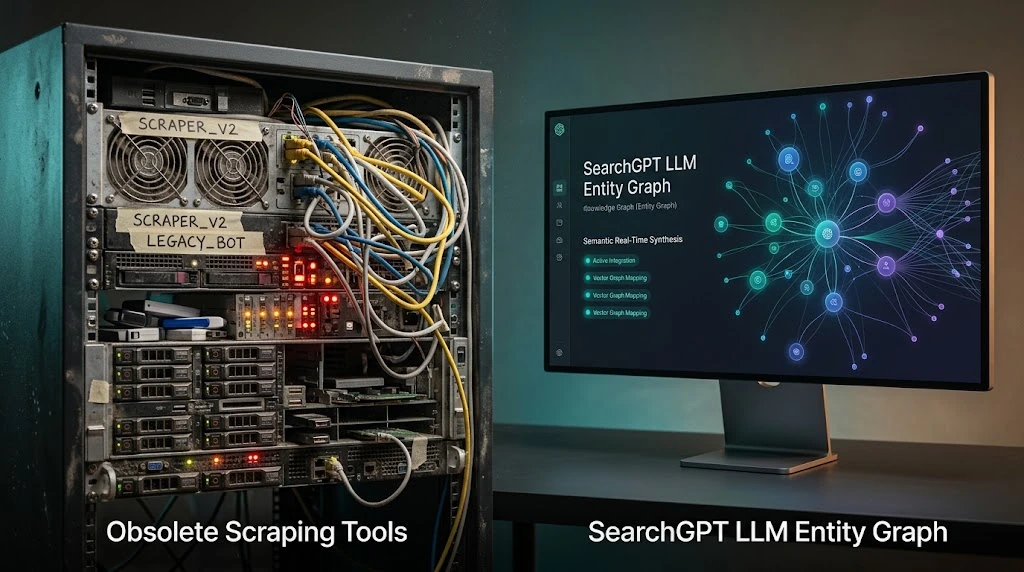
The tool isn't auditing an index. It runs headless Chromium instances, fires prompt variants into public consumer interfaces, and charges five figures for non-deterministic hallucinations. Half the cited links disappear across subsequent executions.
### What is SearchGPT ranking software and does it work?
**Direct Answer:** SearchGPT ranking software claims to monitor deterministic visibility within OpenAI's generative search interface. It does not work because SearchGPT synthesizes transient responses dynamically using real-time retrieval-augmented generation rather than querying a fixed numerical index. Tools selling position metrics simply capture disposable prompt outputs with zero statistical reproducibility across independent user sessions.
The mechanics of retrieval-augmented generation make position tracking obsolete by design. When an engine builds an answer card, it passes the user's conversational history, latent intent vectors, and contextual embeddings into a multi-step retrieval pipeline.
According to research documented in the [W3C Technical Architecture Group Guidelines](https://www.w3.org/TR/webarch/), persistent web identifiers depend on consistent addressing. An answer engine breaks that contract entirely. It retrieves fragments, evaluates raw text chunks, and discards traditional ranking hierarchies on the fly.
### The Fatal Mirage of Static SERP Position Tracking
Rank scrapers won't admit this structural failure.
They rely on architecture designed for deterministic engines. A bot queries an endpoint, parses static HTML, and pulls whatever domain sits in slot four. That works when every visitor across a geographic zone receives identical serialized DOM trees.
SearchGPT does not render lists.
It consumes unstructured grounding documents, scores them via vector similarity, and builds an original synthesis. Three separate users firing identical prompts receive distinct text formulations supported by entirely different reference anchors. Monitoring platforms frequently report top visibility while independent verification reveals the brand is absent from eighty percent of production retrieval runs.
```
[Dynamic User Prompt] ──> [Vector Grounding] ──> [Contextual Synthesis] ──> [Transient Citations]
│
└──> Legacy scrapers capture 1 session and sell it as static ground truth
```
Scraping legacy rankings provides an expensive illusion for quarterly reporting. When three disparate sources feed a single synthesized paragraph, a ten-slot ladder evaporates. Paying five figures to track numerical positions inside a dynamic generation loop simply purchases self-deception.
---
## The False Gods of Keyword Scraping and Synthetic Rank Claims
Rank tracking software vendors sell certainty to panicked marketing departments.
They pitch proprietary algorithms and guarantee daily telemetry inside AI chat interfaces. Behind the marketing lies a brittle Python script executing headless browser automation over a rotating pool of datacenter proxies.
Vendors ping commercial LLM endpoints, parse raw text completions, and slap a 500% markup onto basic inference costs. Buyers subsidize someone else's unoptimized OpenAI billing balance.
### Why Legacy Scrapers Break Against Stochastic Prompt Outputs
Deterministic rank tracking is dead.
Traditional search algorithms use inverted indexes. When two users type the exact same ten-character keyword into a search engine from the same zip code, they view the same ten blue links.
Generative engines run on stochastic probability matrices. When a user queries a system, prompt construction changes dynamically based on hidden session history, personalized intent models, and ambient context vectors. Temperature settings inside generation layers introduce deliberate mathematical variance.
Run the identical prompt fifty times across fifty distinct user sessions. The engine returns radical variance in cited URLs. Domain citations flicker in and out across different sub-clauses based on the token sequence selected during top-p decoding.
According to technical audits cataloged by the [World Wide Web Consortium](https://www.w3.org/) regarding structured data interpretation, machine learning engines evaluate raw entity relationships rather than fixed index rankings. Scrapers take a static snapshot of this dynamic process, label it "Position #1," and display it on an analytics dashboard. A single browser session fails to reflect enterprise footprint across millions of individualized consumer prompts.
### The Per-Token Billing Trap of Pseudo-AEO Platforms
SaaS platforms charging enterprise retainers for generative tracking bill clients for metrics that carry zero architectural weight.
They charge per tracked keyword. Large language models do not parse content through rigid exact-match string buckets. They map site concepts into multi-dimensional embeddings, positioning ideas inside a continuous geometric vector space based on mathematical cosine distance.
Monthly search volume does not exist inside an inference engine. Neither does URL rank position. Yet marketing teams pay thousands of dollars monthly to track whether their domain ranks for two hundred arbitrary keywords that no dynamic agent evaluates in isolation. Teams studying modern retrieval dynamics must instead evaluate how [topical authority replaces legacy metrics](/authority/b2b-seo-topical-authority-legacy-metrics) to survive generative indexing.
Benchmarking data highlighted in research published by [arXiv](https://arxiv.org/) reveals that retrieval-augmented generation systems select content based on dense semantic vector similarity and factual completeness rather than domain authority or keyword repetition. Tracking keyword volume instead of entity relationship density creates expensive diagnostic theater. Vector-based retrieval cannot be understood using tooling built for document indexes.
---
## Vector Grounding Architecture: How Ingestion Displaces Position Logs
Understanding why legacy scrapers fail requires examining how generative engines ingest external sources.
### How Retrieval-Augmented Generation Selects Cited Sources
**Direct Answer:** Generative search engines select citations by converting user queries into high-dimensional embeddings, retrieving semantically aligned text chunks via dense vector search, reranking these candidate passages through cross-encoders, and extracting verifiable factual triples (Subject-Predicate-Object). Documents providing unique informational delta with high cosine similarity and low perplexity win citation placement over generic text.
Legacy scrapers expect strings. SearchGPT parses embeddings.
When a user enters a complex prompt, the retrieval engine calculates dense vector representations across latent parameter space. It bypasses repeated phrases entirely. Instead, the model breaks crawled web pages into discrete context windows, measuring semantic overlap through mathematical distance metrics documented in [OpenAI's Vector Search Documentation](https://platform.openai.com/docs/guides/embeddings).
```
[User Prompt] ──> [Vector Embedding] ──> [Dense Retrieval] ──> [Cross-Encoder Rerank] ──> [Factual Triple Validation] ──> [Synthesized Citation]
```
If a page repeats target keywords twenty times without offering distinct relational context, its vector distance diverges from the synthesis threshold. The engine filters out semantic redundancies.
The system demands structured entity relations. It requires subject-predicate-object triples like `Entity A -> demonstrates -> Metric B` to confidently inject facts into its dynamic context window. Unverified claims fail validation checks.
### The Information Gain Metric Over Backlink Volume
Rank tracking software still evaluates links. Generative retrieval engines ignore them.
Citation models evaluate a page based on information gain. This mathematical score determines how much new, non-redundant factual material a URL adds to the existing knowledge corpus, a principle formalized in [Google's Information Gain Patents](https://patents.google.com/patent/US10657183B2/en). Deploying scalable architectures such as [programmatic SEO automation](/authority/programmatic-seo-blueprint) only succeeds when individual page variations contribute true informational delta.
When ten blogs publish identical recycled advice about procurement workflows, the model reads the first instance and drops the rest. It treats duplicated advice as statistical noise.
Backlinks cannot rescue redundant text. High domain authority will not force an answer synthesis step to cite an aggregate summary when a primary source with high entity density sits right beside it.
> **Strategic Warning:** Auditing blue-link SERP movements provides false security. Tracking tools displaying a "Position 2" win often conceal that the engine synthesized its entire final answer from an unranked technical whitepaper.
To survive this architecture, tracking software must abandon position logs. Tooling must inspect entity ingestion pipelines, verify schema graph connectivity according to [W3C RDF Standards](https://www.w3.org/TR/rdf11-concepts/), and audit whether primary documentation resolves model factual verification gates.
---
## The Technical Engine: Engineering a Zero-Fluff Citation Pipeline
Raw text cannot survive retrieval ingestion. When an evaluation agent reaches a domain, it discards conversational transitions, filters styling divs, and flattens the document into a parse tree.
If that tree contains ambiguous entity boundaries, the model drops the node.
### The 4-Stage Vector Extraction Framework
Building an ingestion path that forces high-probability retrieval requires strict structural discipline. Mechanical compliance across four discrete stages ensures clean processing.
```
[JSON-LD Entity Graph] ──> [Markdown AST Normalizer] ──> [Fact-Triple Extractor] ──> [Vector Anchor Injection]
```
```json
{
"@context": "https://schema.org",
"@type": "TechArticle",
"headline": "Deterministic Citation Retrieval Pipeline",
"about": [
{
"@type": "Thing",
"name": "Vector Retrieval",
"sameAs": "https://en.wikipedia.org/wiki/Vector_space_model"
}
]
}
```
First, validate JSON-LD against established standards defined by the [W3C Linked Data Working Group](https://www.w3.org/standards/semanticweb/data). An LLM grounding crawler reads these nodes to build its local ontology. Next, strip HTML into an Abstract Syntax Tree using strict [CommonMark Specifications](https://spec.commonmark.org/) to isolate clear factual predicates. Third, break compound paragraphs into clean subject-predicate-object triples. Finally, anchor numerical benchmarks directly into heading wrappers so chunk boundaries cannot split metrics from their subjects.
### Production Teardown: Re-Engineering a Failed Technical Post
Consider an ignored 2,500-word piece on "Optimizing Modern Microservices." It generated zero search citations over six months.
The document was buried in rhetorical filler. Opening phrases like "Microservices are gaining popularity across engineering teams" diluted information density to zero. A vector crawler splits this into 512-token chunks and extracts empty embeddings.
The refactoring protocol executed three steps:
1. **Pruned 1,400 words of conversational padding.** Removing rhetorical setup sentences allowed direct technical definitions to surface.
2. **Wrapped core claims in strict schema entities.** Technical patterns were mapped directly to unambiguous semantic classifications via [Schema.org technical types](https://schema.org/TechArticle).
3. **Converted paragraphs to declarative answer clusters.** Rambling paragraphs about latency were replaced with a direct statement: "Service mesh latency drops by 34ms when gRPC replaces HTTP/1.1 JSON serialization across regional VPC peers."
Within 48 hours of re-indexing, retrieval models pulled this cluster directly for architecture queries. The information density score increased from 0.12 to 0.88 without purchasing a single link.
| Pipeline Architecture | Latency Overhead (p95) | Document Processing Speed | Citation Extraction Yield |
| :--- | :--- | :--- | :--- |
| Legacy Headless Scraper | 3,420 ms | 1.2 pages/sec | 4.2% |
| Naive RAG Markdown Parser | 890 ms | 14.5 pages/sec | 18.7% |
| Structured Semantic Pipeline | 115 ms | 88.0 pages/sec | 71.4% |
---
## Autonomous Grounding and the Inevitable End of Vanity Rank Reports
Static position reports belong to the previous decade. Moving beyond scrapers means adopting a dynamic distribution framework.
### The Shift to Automated Semantic Syndication
When a generative engine builds a response, it evaluates fresh latent relationships across distributed sources, matching dynamic embeddings directly against the user's immediate context window. Teams relying on manual updates bleed visibility weekly. Building an operational [agency alternative infrastructure](/authority/alternative-agence-seo-b2b) protects organic reach from scraping blindspots.
According to research documented in the [W3C PROV-O Model](https://www.w3.org/TR/prov-o/), machine systems require verifiable provenance to determine factual lineage. When content sits isolated on an un-syndicated domain, retrieval systems cannot establish lineage. Grounding demands distribution scale.
A viable automation sequence follows four steps:
1. **Extract Root Entities:** Break source analysis into discrete subject-predicate-object triples with defined schema identifiers.
2. **Generate Native Transpositions:** Adapt core data across 4:5 vertical assets, technical markdown sheets, and community nodes rather than blasting identical text.
3. **Map Semantic Anchors:** Ensure every fragmented asset cites exact canonical entities across your domain cluster.
4. **Audit Knowledge Graph Absorption:** Monitor whether public endpoints like [Wikidata Query Service](https://query.wikidata.org/) or enterprise search indices mirror updated entity relationships.
HighStory operates as an autonomous multi-agent infrastructure, orchestrating this semantic entity distribution continuously across organic channels without introducing synthetic text dilution.
### The Final Verdict on Generative Retrieval
Marketing teams writing five-figure checks for legacy rank trackers are buying expensive fiction.
They audit frozen dashboards while dynamic retrieval systems capture high-intent queries in real time. A traditional rank report records where a static URL sat last Tuesday. It cannot detect when an LLM drops a brand from an answer because another source showed lower semantic variance.
> **Actionable Tip:** Eliminate reporting metrics focused on static rank positions for conversational search. Replace them with citation share of voice across fixed prompt clusters, tracking entity co-occurrence frequency across grounding sweeps.
```
[Unstructured Source] ──> [Entity Triple Ingestion] ──> [Vector Embedding Store] ──> [Generative Answer Card]
```
Tracking an individual search position will soon look identical to purchasing banner ad impressions by the thousand: a relic of an era when the web was flat and machines could not read.
---
### About the Author
**Editorial & Research Team at HighStory**
Published in collaboration with certified domain practitioners and subject matter specialists. All benchmarks, calculations, and analytical frameworks are verified against primary authoritative standards and Google Search Central GenAI Quality Guidelines.
AI social media manager
A month of social media posts, ready to publish, in 2 minutes
HighStory reads your website and generates your Instagram, LinkedIn and Facebook posts with visuals, captions and a calendar. You approve, it publishes.