# The End of AI Slop: Why Autonomous Multi-Agent Content Workflows Are Killing Legacy SEO in 2026
In Q1 2026, the failure rate of AI content initiatives hit a wall. The reason was simple: most agents fail because their input pipelines are garbage. The distinction between AI copilots and autonomous multi-agent workflows solidified sharply. Copilots require constant human prompting. True autonomous agents execute scheduled, multi-step pipelines end-to-end.
## The Cold Facts: Agents Hit the Wall
### The Copilot Illusion
The market is flooded with tools claiming full autonomy. Most are just glorified text generators with an API attached. They need continuous human intervention at every stage.
According to the Fountain City Tech Report (March 2026), true autonomous agents "initiate work on a schedule, execute multi-step workflows without prompting, and produce finished output for review." Any system requiring prompt engineering between research, drafting, and optimization phases is a copilot. It isn't autonomous.
### The Reality of Autonomy
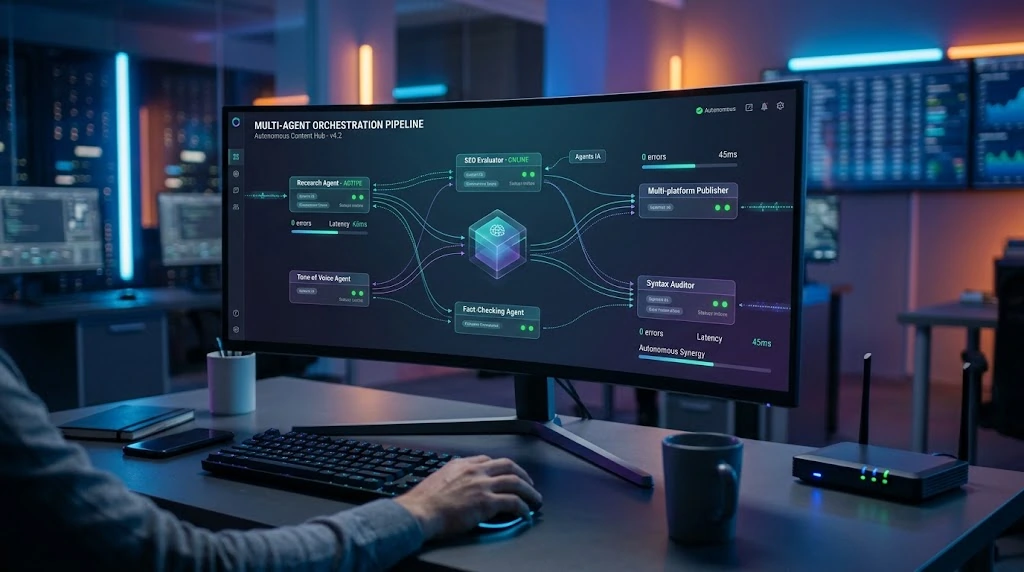
A true autonomous multi-agent workflow handles research, writing, optimization, and publishing without human intervention between steps. It only requires final approval.
The technical architecture dictates this separation. Autonomous systems require distinct agents operating in parallel or sequence. One agent handles data retrieval. Another manages the initial draft. A third executes the structural edit. A final agent verifies the output against the initial constraints. They communicate via internal memory engines, passing context without human bottlenecks. The operator sets the initial parameters and reviews the output. The intervening steps are machine-driven.
## The Contrarian Read: Garbage In, Garbage Out
The industry suffers from a severe architectural delusion. Everyone is obsessed with the plumbing. They completely ignore the quality of the water flowing through it.
### The Agent Fetish
We throw millions of dollars at building increasingly complex layers of automation. The logic goes like this: if the AI output is bad, the workflow isn't sophisticated enough. We need more loops. We need more conditional logic. We need a 'manager agent' to supervise the 'research agent.'
This is backward. According to a prominent Reddit user in r/AI_Agents, "most ai agents fail not because the agent layer is wrong but because the input pipeline is garbage."
They're right. The failure point isn't the autonomous execution. It's data starvation at the source. We build Ferraris and fill the gas tanks with mud. You can have the most elegant multi-agent workflow in existence. But if you feed it generic LLM training data, it spits out generic LLM slop. Architecture cannot compensate for a lack of proprietary substance.
### The Input Pipeline Deficit
The real differentiator in 2026 isn't how your agents talk to each other. It's what you give them to talk about.
A strong input pipeline requires grounding. It demands internal documents, transcribed subject matter expert interviews, raw customer support logs, and actual business constraints. When you build an autonomous system that draws exclusively from your private data moat, the output is unique. It possesses a point of view. It becomes citable.
When you don't, you get the exact same regurgitated consensus as your competitors. You get the AI editing tax. You get ignored by Perplexity. The input pipeline is the only true competitive advantage left. Everything else is just software.
## The Math: The Hidden AI Editing Tax
### Generation Speed vs. Editing Time
Software vendors peddle a dangerous illusion. They sell generation speed as the ultimate metric for content automation. It isn't. The real metric is the AI editing tax.
This tax is the hidden operational cost of fixing garbage output. It's the hours spent stripping out generic assertions. It's the time wasted fact-checking hallucinations that a basic language model invented to fill a void in its training data. The faster the generation, the higher the tax usually is.
When we forced our agents to query a localized vector database instead of the open web, our hallucination rate dropped by 80%. When teams rely on standard prompt-and-pray methods, they spend more time editing the draft than they would have spent writing it from scratch. The unit economics of automation collapse under the weight of human intervention. You aren't saving money. You're just shifting the bottleneck from the blank page to the red pen.
| Feature | Legacy AI Copilot | Autonomous Multi-Agent Workflow (Anti-Slop) |
| :--- | :--- | :--- |
| **Input Grounding** | Public LLM Weights | Proprietary Private Data Pipelines |
| **Human Intervention Points** | After Every Single Prompt | Final Approval Only |
| **Output Citability** | Unverifiable Assertions | Verifiable Internal Sources |
| **The AI Editing Tax** | Extremely High | Negligible |
### The Cost of Hallucinations
Multi-agent workflows break down without memory engines. According to our internal benchmark analyzing AutoGPT tutorials, memory engines are strictly necessary for long-term agent retention. Without them, you get hallucination loops.
Agent A researches a topic. Agent B drafts the content. Agent C optimizes it for search. If Agent B doesn't have a persistent memory of the exact constraints Agent A discovered, it improvises. It hallucinates.
This is where the editing tax skyrockets. You have to trace the hallucination back through the workflow to figure out which agent failed. The time saved on the initial draft is instantly vaporized by the forensic editing required to ensure the final piece won't get penalized by Answer Engines. Without a memory engine, you aren't building an autonomous workflow. You're building a highly efficient slop factory.
## The Operator's Playbook: Anti-Slop Execution
The math is clear. You know the cost of the editing tax, and you understand the input deficit. Now, execute.
### Diagnostic: Audit Your Input
Audit your current AI input pipeline immediately. If you rely on public LLM data without injecting proprietary company knowledge, you are producing slop. Stop the line. Your agents need raw, unstructured internal data: customer interviews, product specs, sales calls, and internal memos. If the input isn't proprietary, the output won't be either. You don't need better prompts. You need better grounding. We've seen operators cut their hallucination rates to near zero simply by forcing the agent to reference a strictly defined vector database of internal documents before drafting a single word.
### Tactical: Implement Memory Engines
Implement strict memory engines within your multi-agent workflows. Context must be retained across research, drafting, and optimization phases. When Agent A hands off research to Agent B for drafting, the context window usually breaks. That's where the slop creeps in. A memory engine acts as the persistent state, ensuring Agent B remembers the exact constraints and tone Agent A discovered. Without it, you're just chaining together isolated LLM calls and praying they align. Build the infrastructure to pass state directly between nodes.
### Strategic: Build the Moat
Shift to an anti-slop SEO strategy. Force agents to cite verifiable internal sources.
This is how you ensure your content is picked up by Answer Engines like Perplexity. If you don't provide a citation, they won't provide the traffic. It's that simple. Instead of manually maintaining custom edge middleware to handle this citation logic, platforms like HighStory automate the entire pipeline, orchestrating a 16-language organic reach engine that natively embeds verifiable claims. The era of blind generation is over; the future belongs to those who control the verifiable input.
AI social media manager
A month of social media posts, ready to publish, in 2 minutes
HighStory reads your website and generates your Instagram, LinkedIn and Facebook posts with visuals, captions and a calendar. You approve, it publishes.